Why Deleting a Single Post Doesn’t Solve the Problem of Personal Data
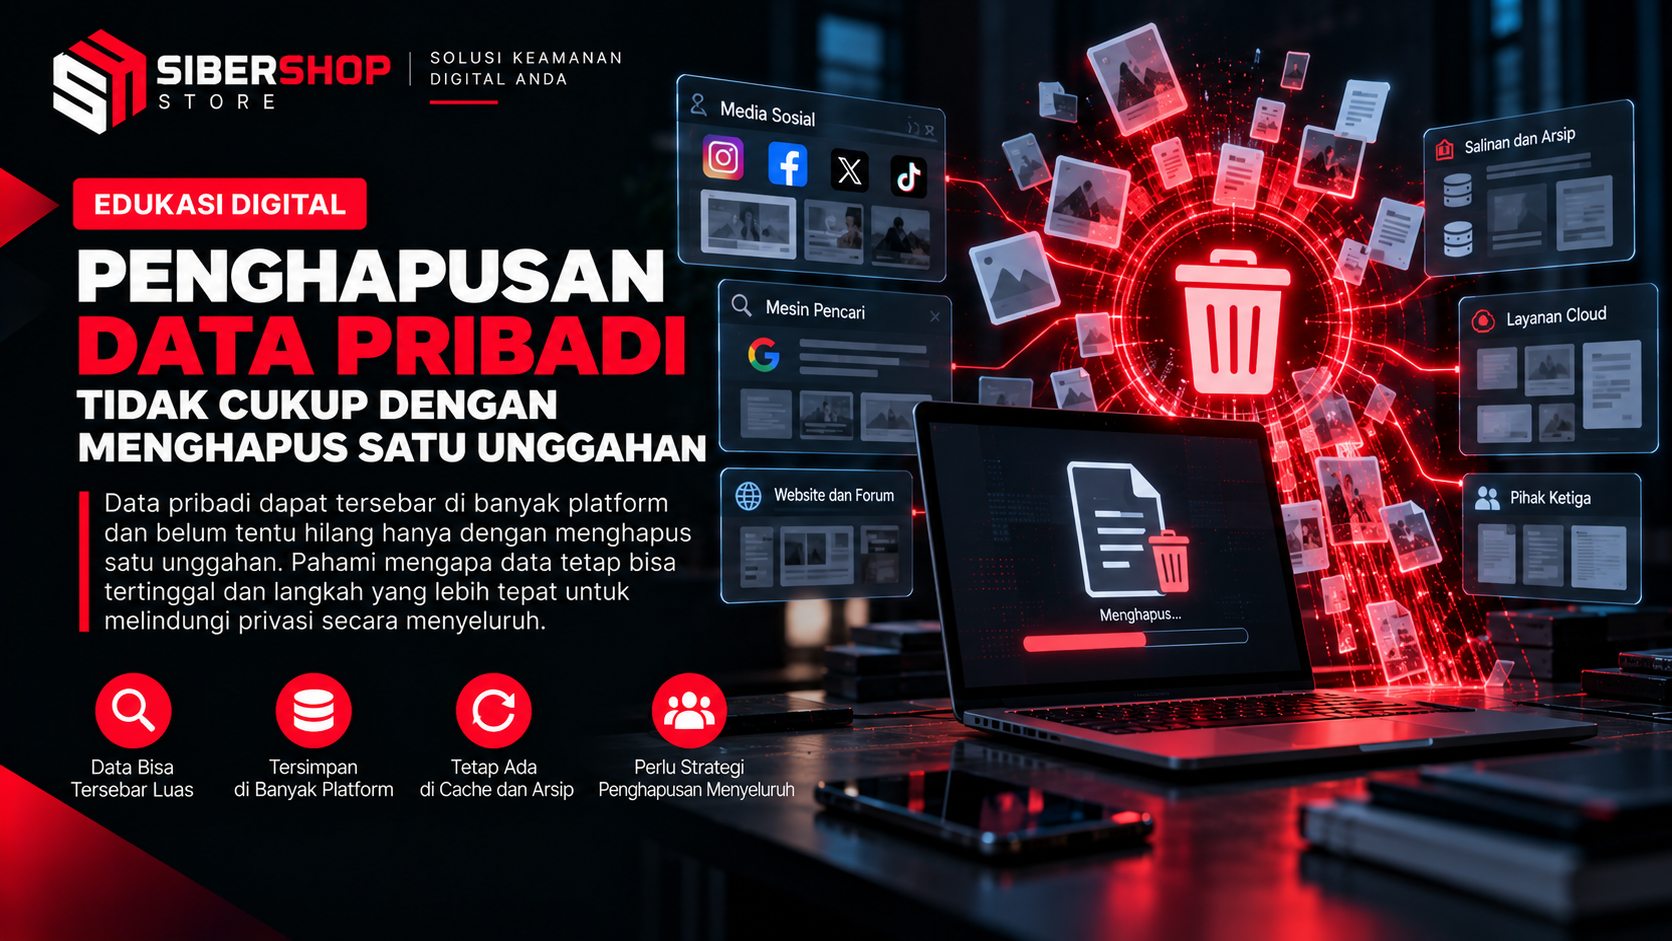
Many people assume that the issue of personal data is resolved once a problematic post is removed from its original page. In reality, information that has already circulated on the internet rarely remains in just one place. That data can be copied, indexed, archived, and reposted by parties who have never had any connection to the data owner. Therefore, deleting personal data by targeting just a single link often leaves traces that can still be found weeks later. This article outlines these layers of dissemination and explains why a professional approach starts with mapping, not with a hasty removal request.
The Original Source Is Only the First Layer
The original source is the website, social media account, forum, or document that first published the data. This is the layer where deletion requests are most commonly submitted, as the source’s administrator has direct authority over the content of the page. However, deleting the original source does not automatically clear other locations that have copied or referenced it. Furthermore, not all sources are easily accessible. There are accounts that the owners can no longer access, websites whose administrators do not respond, and documents uploaded by third parties without the data owner’s knowledge. In situations like this, a formal request to the platform or hosting provider is often a more realistic approach than contacting the uploader directly.
Search Results, Caches, and Third-Party Archives
Once a page is published, search engines typically record the title, text snippet, and a temporary copy called a cache. That’s why personal data may still appear in search results even after the original page has been deleted. Old snippets can persist until search engines update their indexes, and that process isn’t always quick. Beyond search engines, there are web archiving services and aggregator sites that store copies of pages independently. These copies are controlled by third parties with their own policies, so requests must be submitted separately and follow the terms they set. Ignoring this layer makes the data appear to be lost when it can still be found using specific keywords.
Reposting by Third Parties
The most difficult layer to control is redistribution. Screenshots, reposts on other accounts, discussion forums, chat groups, and mirror sites may contain the same data without linking back to the original source. Each copy stands as new content with a different manager, so each requires its own approach. The longer the data circulates, the greater the likelihood that new copies will appear in unexpected places. Time is therefore a critical factor, and delayed handling generally requires a broader scope of work. For a more detailed overview of how personal information spreads, please read our article on digital footprints and the dissemination of personal data on the internet.
Mapping, Route Selection, and Monitoring
Professional handling begins with mapping all these layers before a single request is submitted. Mapping reveals where the data is located, who manages it, and how quickly it spreads. Based on this map, the team determines the appropriate course of action for each finding. Some issues can be addressed through formal requests to the platform, others require filing an abuse report, and certain cases may need to proceed through legal channels if necessary. After a request is submitted, monitoring continues because new copies may appear and search results may change. Without monitoring, a fix at one point can easily be undermined by the reappearance of the same data elsewhere.
Documenting Evidence and Prioritizing High-Risk Data
Evidence must be documented from the outset, before the content is removed or altered. Screenshots showing the date and page URL, the time the finding was made, and details regarding the data subject’s relationship to the content form the basis for every request. Platforms and authorities generally require clarity regarding what is being reported and the rationale behind it. Well-organized evidence also saves time because the same findings do not need to be tracked down repeatedly. Afterward, the data is sorted according to its risk level. Information that reveals a residential address, personal contact details, or family member data is usually prioritized over information with less severe consequences.
It’s also important to understand that the final outcome depends on each platform’s policies and the circumstances of each case. Some requests are processed quickly, some require additional documentation, and others are denied because they do not meet the platform’s requirements. An honest explanation of these limitations helps data subjects maintain realistic expectations from the start. With clear mapping, evidence, and priorities, the effort to delete personal data has a more measurable approach than deleting links one by one.
Contact Us
Contact Us through our official channels.